Speaker-labeled transcription with WhisperX on SageMaker AI
How-To How to actually use this
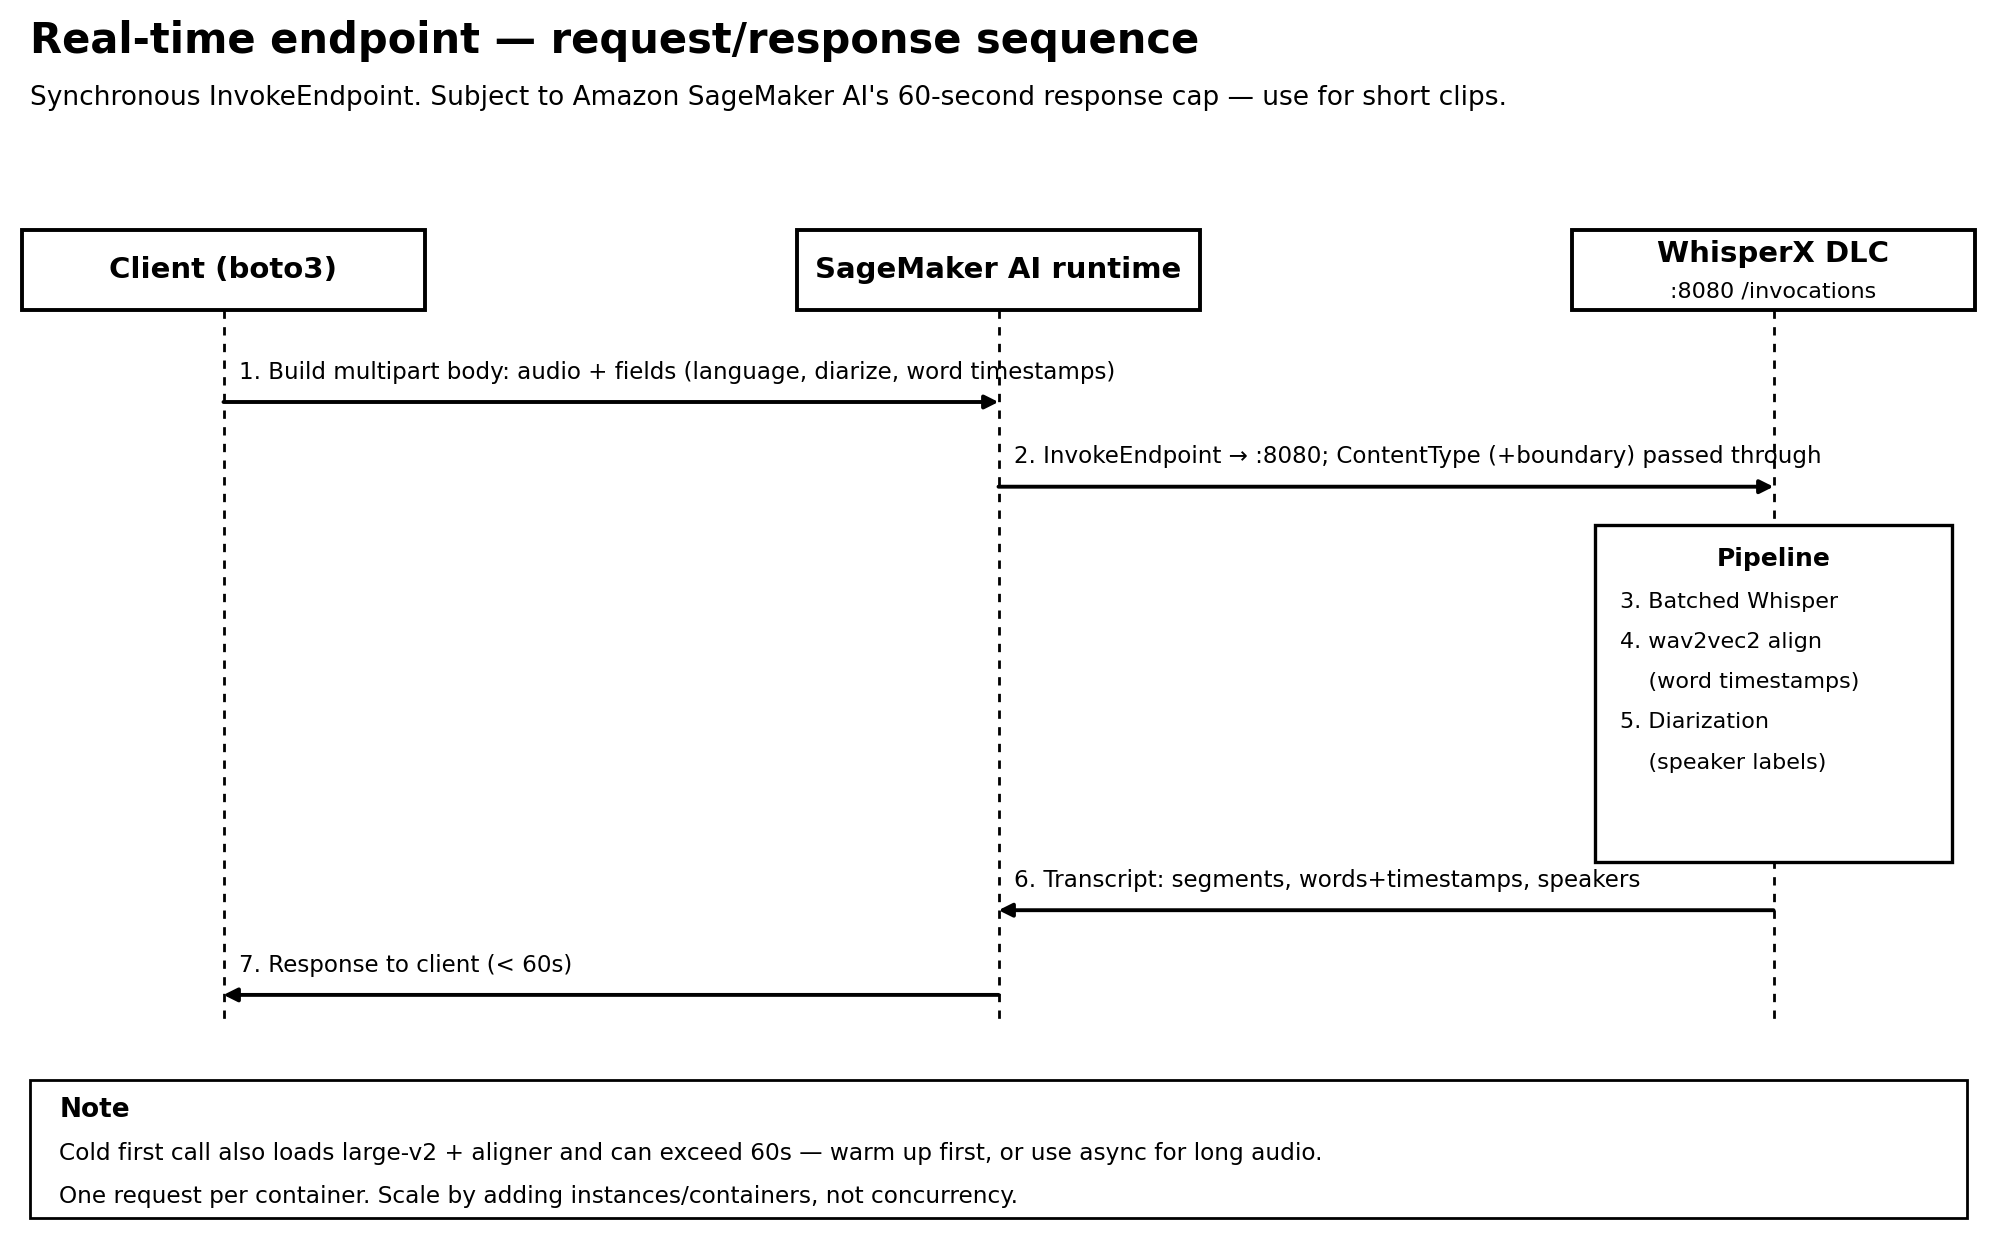
What changed: AWS released a WhisperX Deep Learning Container for SageMaker AI that bundles Whisper, wav2vec2 forced alignment, and speaker diarization into a GPU-ready image for real-time and async endpoints.
How to use it:
- Pull the WhisperX Deep Learning Container image URI from the AWS Deep Learning Containers repository for your target region and GPU instance type.
- Create a SageMaker model pointing to the container image and an S3 location for any custom model artifacts or configuration.
- Deploy the model to a real-time inference endpoint (for low-latency) or an asynchronous inference endpoint (for large audio files) using GPU-backed instances like ml.g5.xlarge.
- Configure auto-scaling policies on the endpoint variant to manage costs during variable traffic.
- Send audio files to the endpoint via the SageMaker InvokeEndpoint or InvokeEndpointAsync API to receive word-level, speaker-labeled JSON transcripts.
Good for: developers building speaker-attributed transcription pipelines on AWS.
The AWS WhisperX Deep Learning Container packages Whisper, wav2vec2 forced alignment, and speaker diarization into a GPU-ready image. Learn how to deploy it to Amazon SageMaker AI real-time and asynchronous endpoints for word-level, speaker-labeled transcription, plus the production details that matter: the GPU AMI pin, scaling, and cost controls.
Read original article on Artificial Intelligence →More in Products & Tools