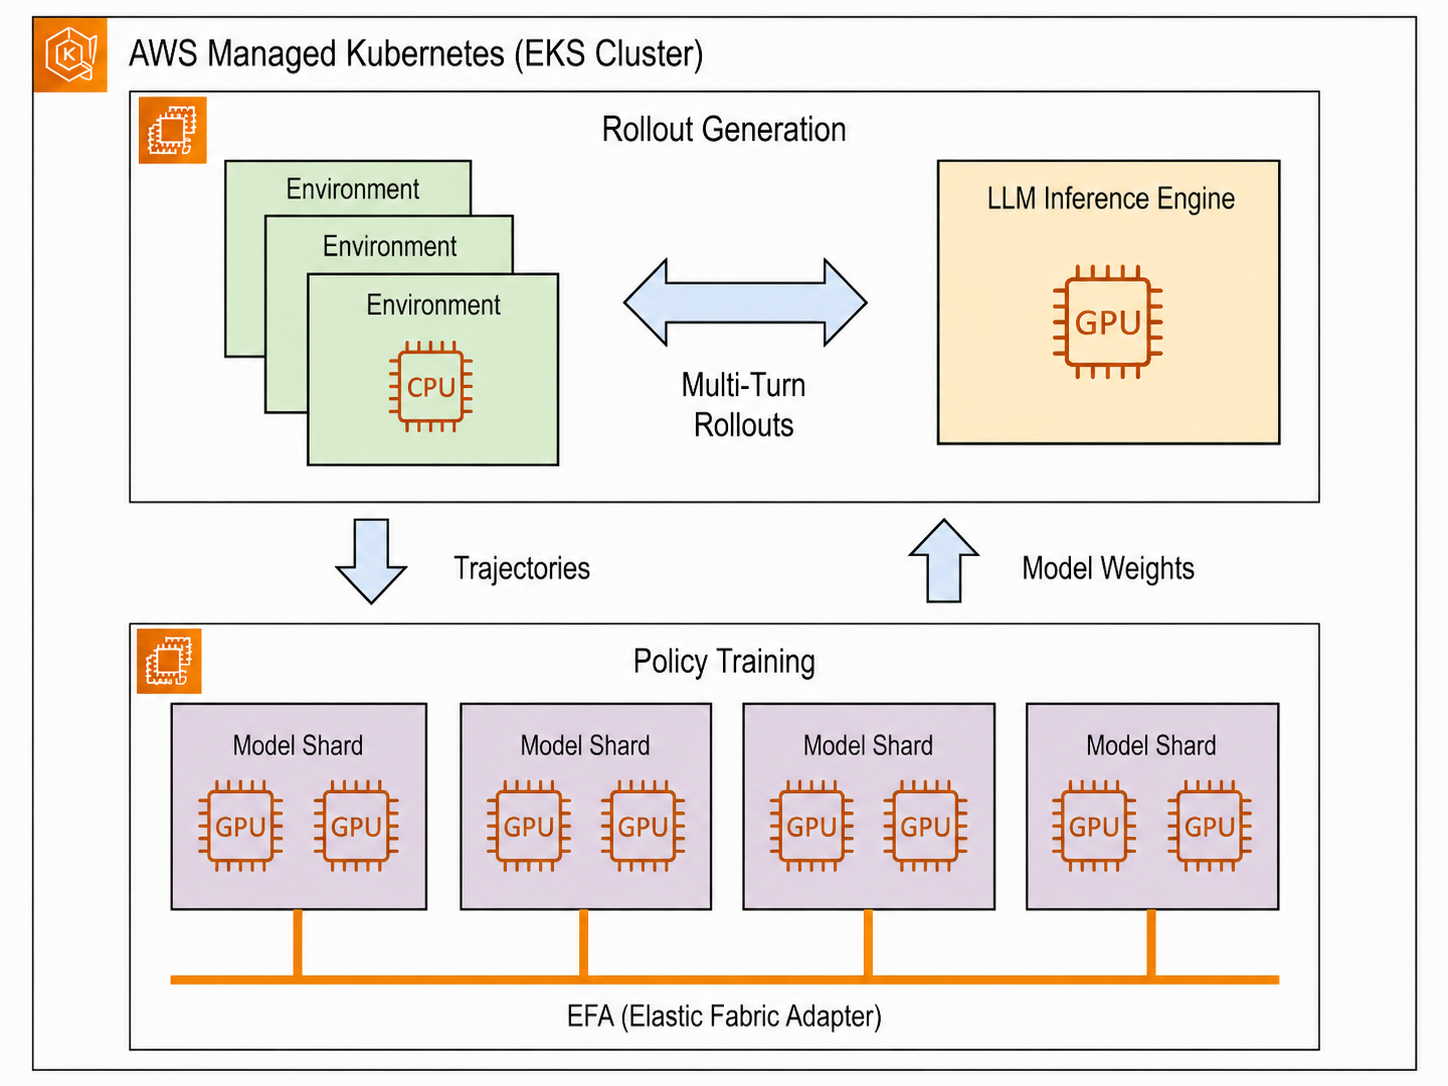
Scaling MoE reinforcement learning on Amazon EKS with EFA and DeepEP with 40% more throughput
How-To How to actually use this
What changed: AWS published a reference architecture using EKS, EFA, and DeepEP that achieves 40% higher MoE RL rollout throughput.
How to use it:
- Provision an EKS cluster with EFA-enabled instances (e.g., p5.48xlarge) and install the EFA device plugin.
- Deploy DeepEP as the expert-parallel communication library inside your training containers.
- Configure your RLHF/GRPO rollout workers to use EFA-backed MPI/NCCL collectives for expert routing.
- Store checkpoints and datasets on Amazon S3 for shared access across nodes.
- Benchmark aggregate rollout throughput against your baseline to verify the 40% gain.
Good for: ML engineers scaling MoE RLHF or GRPO training on AWS.
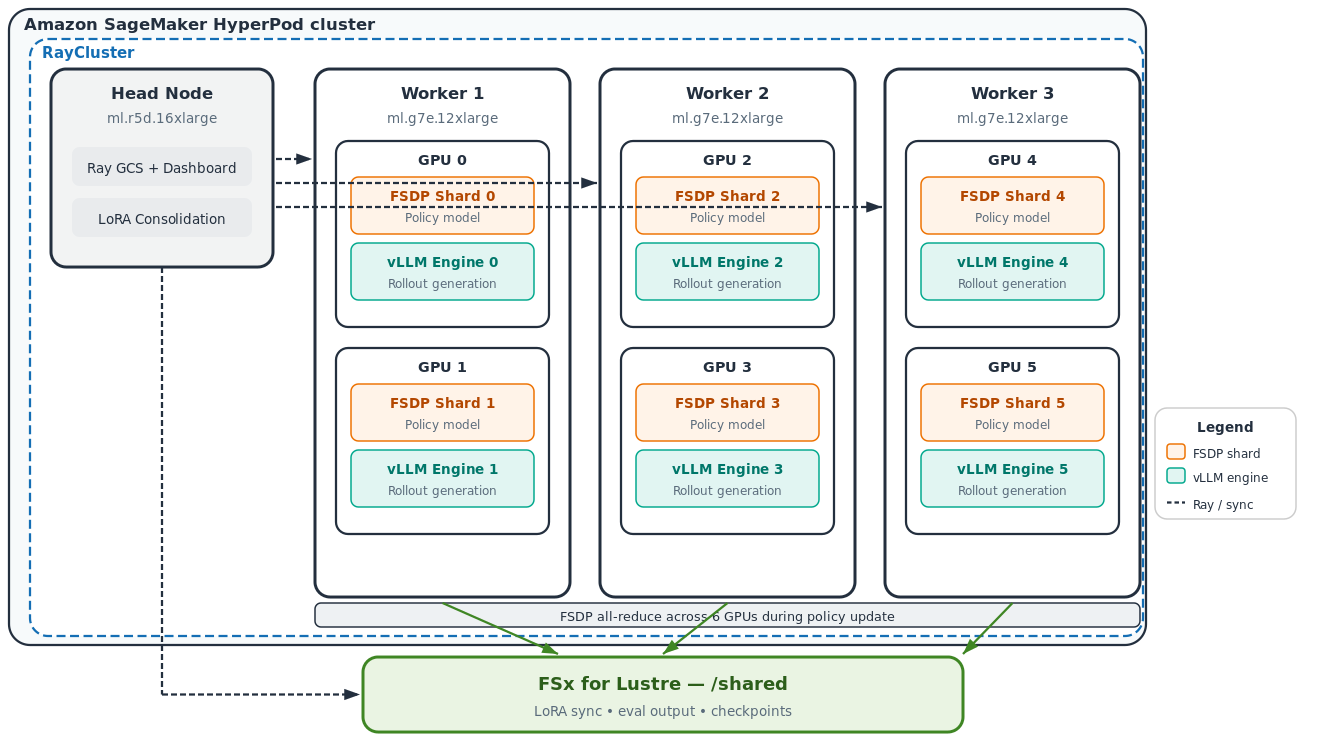
Learn how to scale Mixture-of-Experts (MoE) reinforcement learning on Amazon EKS using Elastic Fabric Adapter (EFA) and DeepEP. This post presents an architecture that combines Amazon EKS, EFA, and Amazon S3 and increased aggregate reinforcement learning rollout throughput by 40% for large-scale RLHF and GRPO training.
Read original article on Artificial Intelligence →