Amazon SageMaker Inference: 2026 year-to-date launches in review
How-To How to actually use this
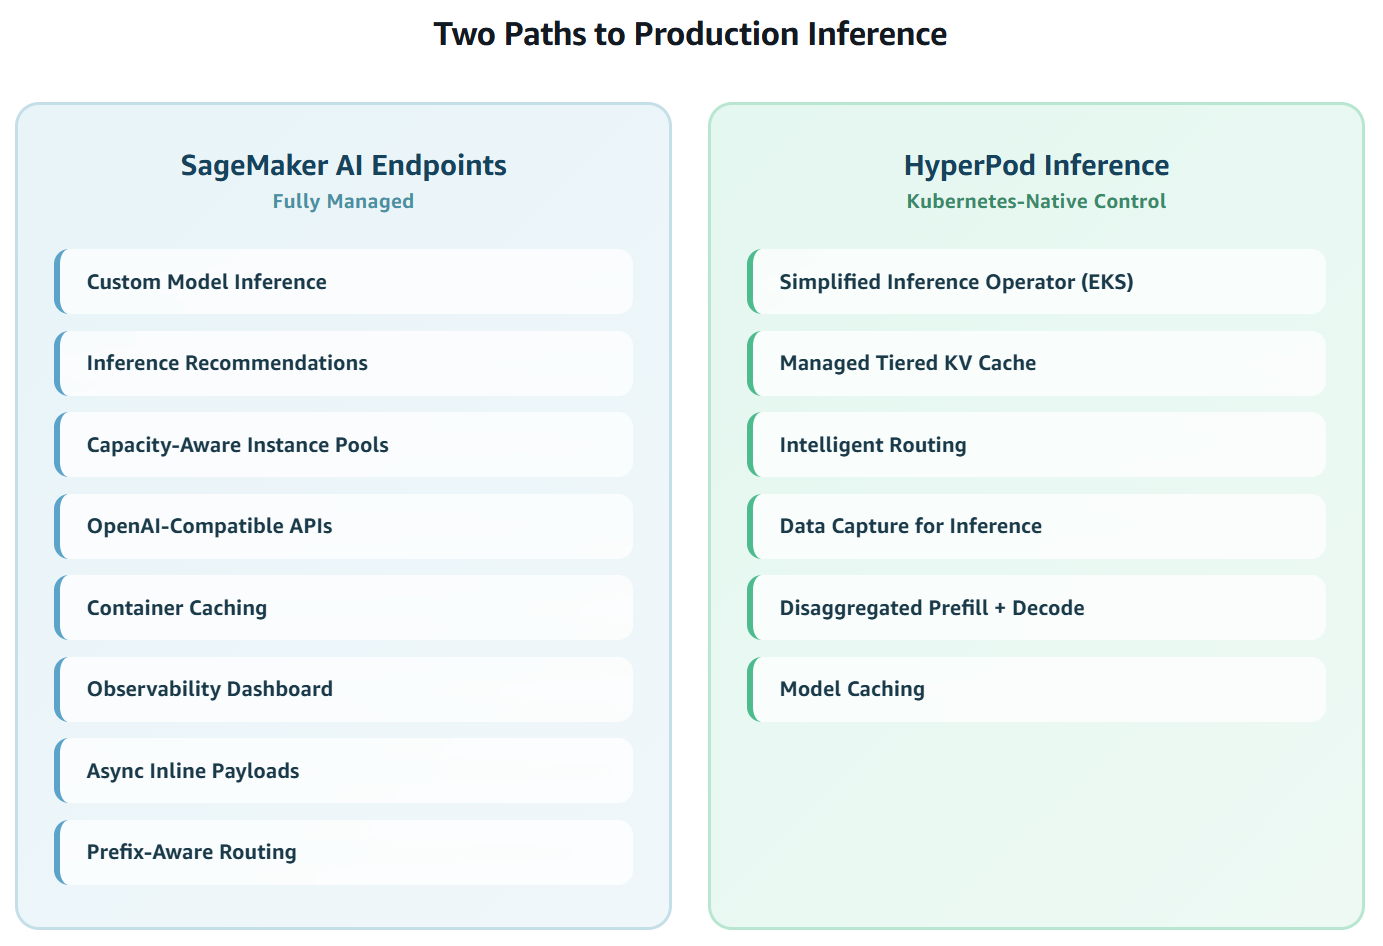
What changed: Amazon SageMaker added 13 new inference capabilities in 2026 across managed endpoints and HyperPod Inference.
How to use it:
- Review the new inference recommendations and capacity-aware instance pool options when planning deployments.
- Use tiered KV caching for workloads with large context lengths.
- Consider disaggregated prefill and decode to separate compute stages.
- Choose managed endpoints or HyperPod Inference based on your control and scale needs.
Good for: ML engineers deploying models on SageMaker.
Amazon SageMaker AI shipped 13 inference launches in year-to-date across two deployment paths: fully managed endpoints and Amazon SageMaker HyperPod Inference. This post reviews each launch, from inference recommendations and capacity-aware instance pools to tiered KV caching and disaggregated prefill and decode.
Read original article on Artificial Intelligence →