Right-size generative AI endpoints with concurrency sweeps on Amazon SageMaker AI
How-To How to actually use this
What changed: You can now run automated concurrency sweeps on SageMaker AI generative AI endpoints to benchmark performance at increasing load levels and right-size your fleet.
How to use it:
- Deploy your generative AI model to a SageMaker endpoint.
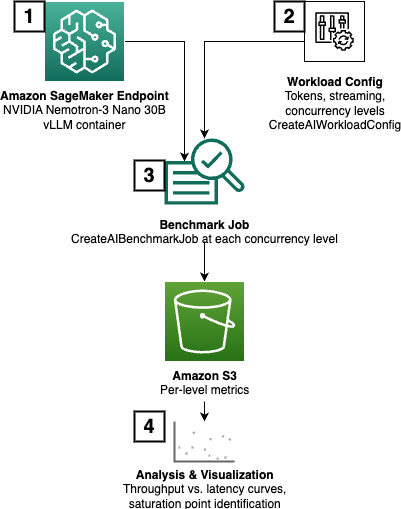
- Use the CreateAIBenchmarkJob API to start an automated concurrency sweep against that endpoint.
- Review the benchmark results showing performance at each load level.
- Use the data to decide the right fleet size for your endpoint.
Good for: ML engineers optimizing endpoint costs and performance.
Concurrency sweeps help you right-size a generative AI endpoint on Amazon SageMaker AI by systematically benchmarking it at increasing load levels. This post walks through deploying a model, running automated concurrency sweeps with the CreateAIBenchmarkJob API, and using the results to make data-driven capacity decisions about fleet size.
Read original article on Artificial Intelligence →