Introducing Amazon SageMaker HyperPod Inference Gateway
How-To How to actually use this
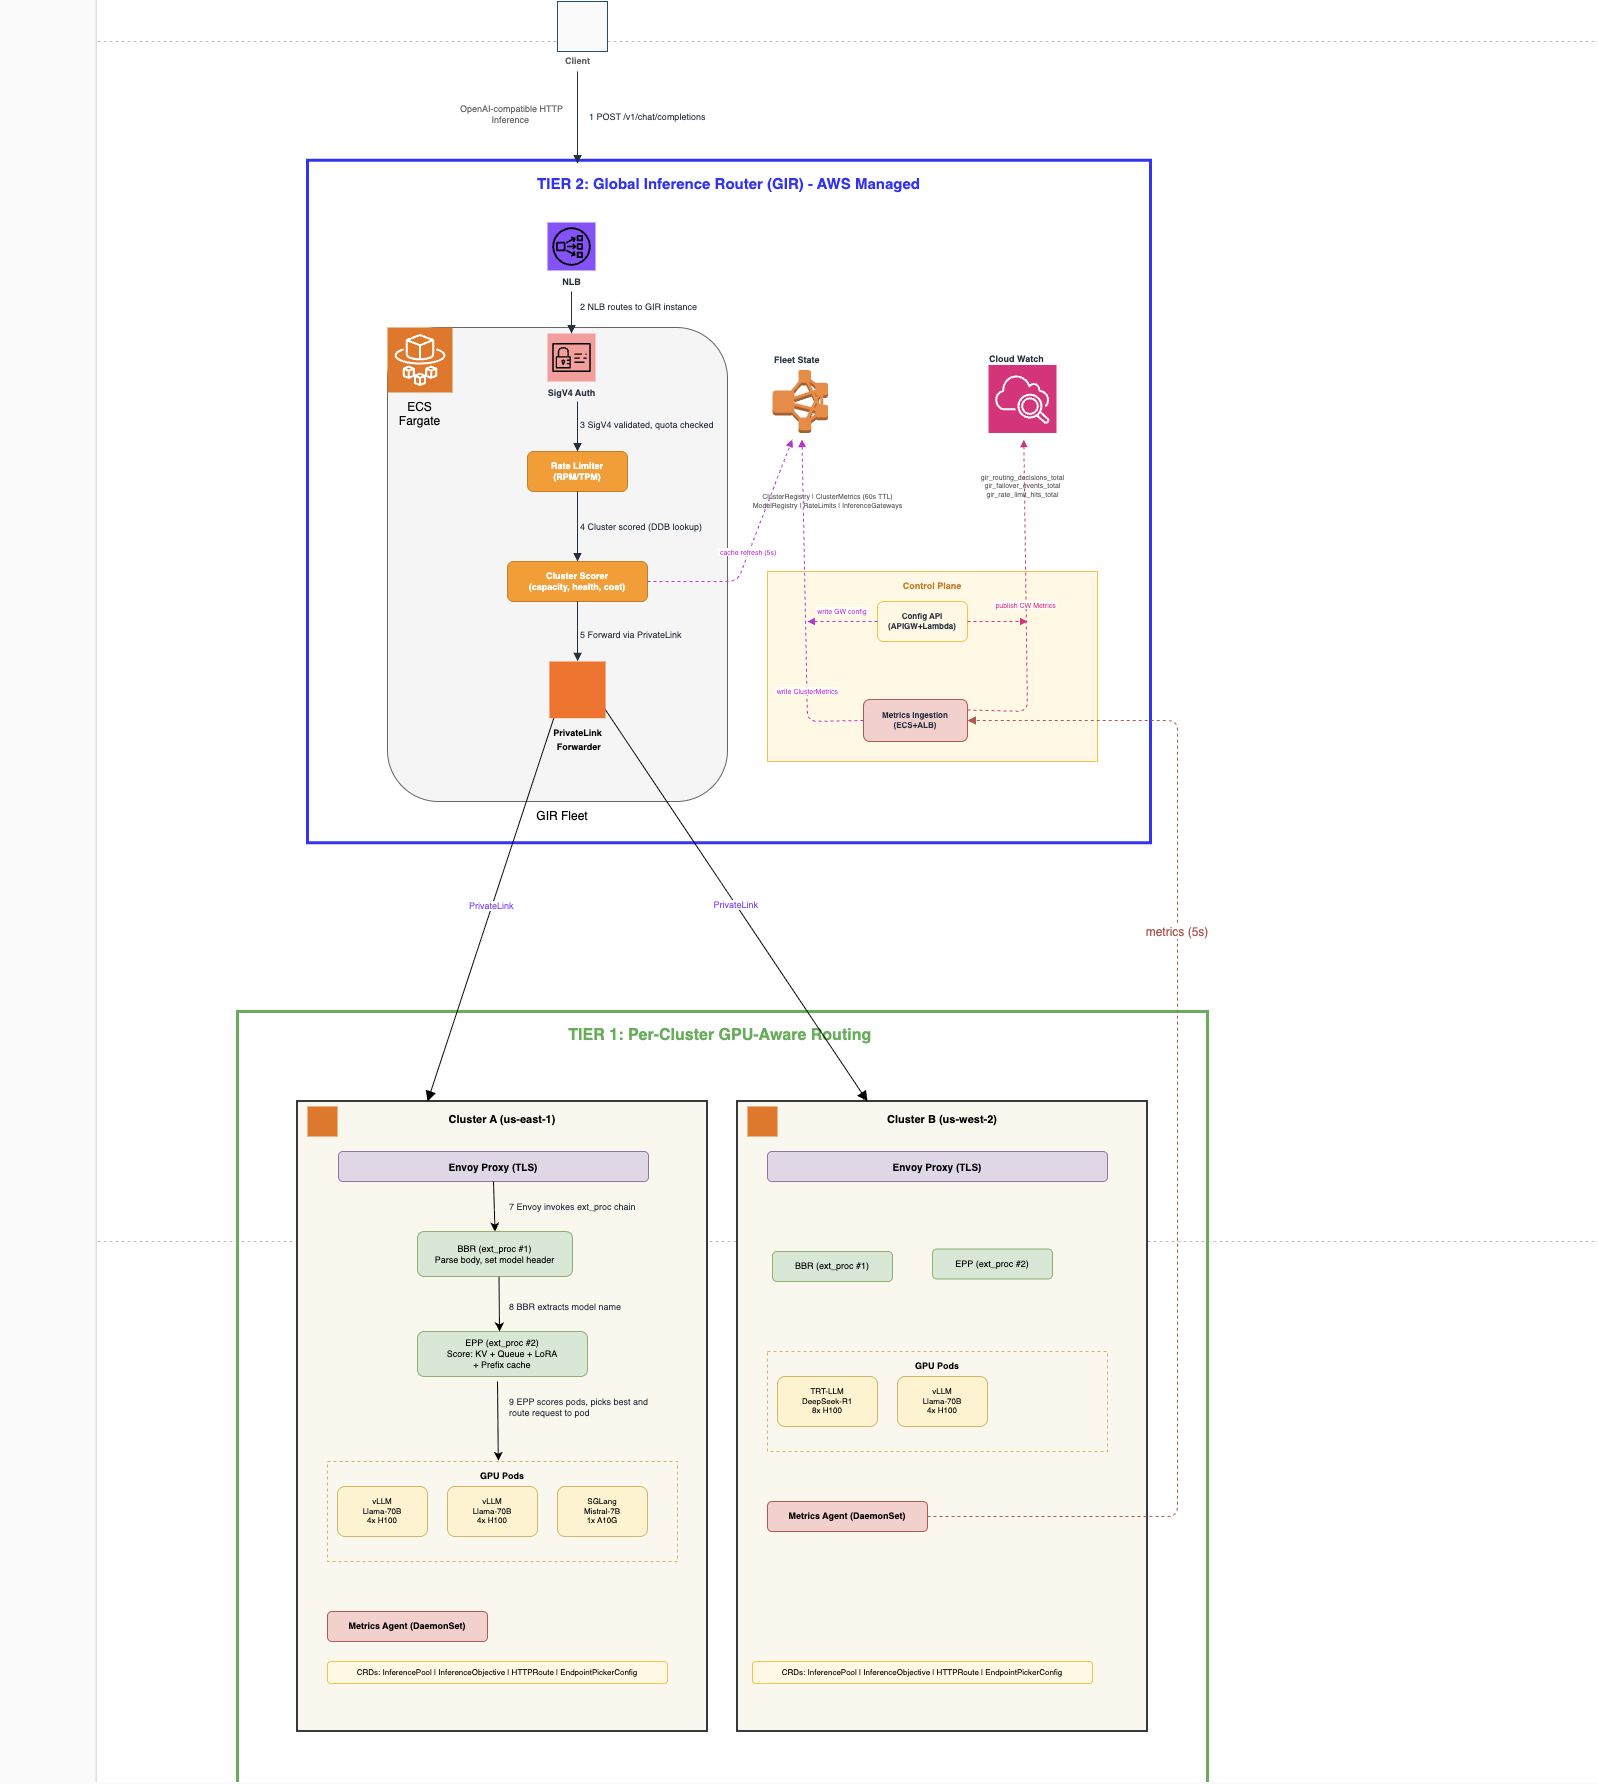
What changed: Amazon SageMaker HyperPod Inference Gateway is a new Kubernetes-native add-on for Amazon EKS that routes inference requests to the best GPU pod using real-time signals, reducing first-token latency by up to 82%.
How to use it:
- Deploy the HyperPod Inference Gateway add-on to your existing Amazon EKS cluster.
- Ensure your model servers are running as pods on the cluster with GPU resources.
- Point your inference client applications to the Gateway's service endpoint instead of individual pods.
- The Gateway automatically routes requests based on real-time GPU load and pod health.
Good for: teams running GPU inference on EKS who need lower latency without modifying models or clients.
Amazon SageMaker HyperPod Inference Gateway is a Kubernetes-native, GPU-aware routing add-on for Amazon EKS. It uses real-time GPU signals to send each inference request to the best-suited pod, cutting first-token latency by up to 82% with no changes to your model servers or client applications.
Read original article on Artificial Intelligence →